AI Doesn't Reward Risk. It Punishes Bad Scoping.
Before you fund it, score your project on these ten dimensions. Or accept the downside.
Read more →How a live AI system on a pharmaceutical market access platform was rebuilt on its own knowledge foundation, and single answers became a working dialogue with the data.
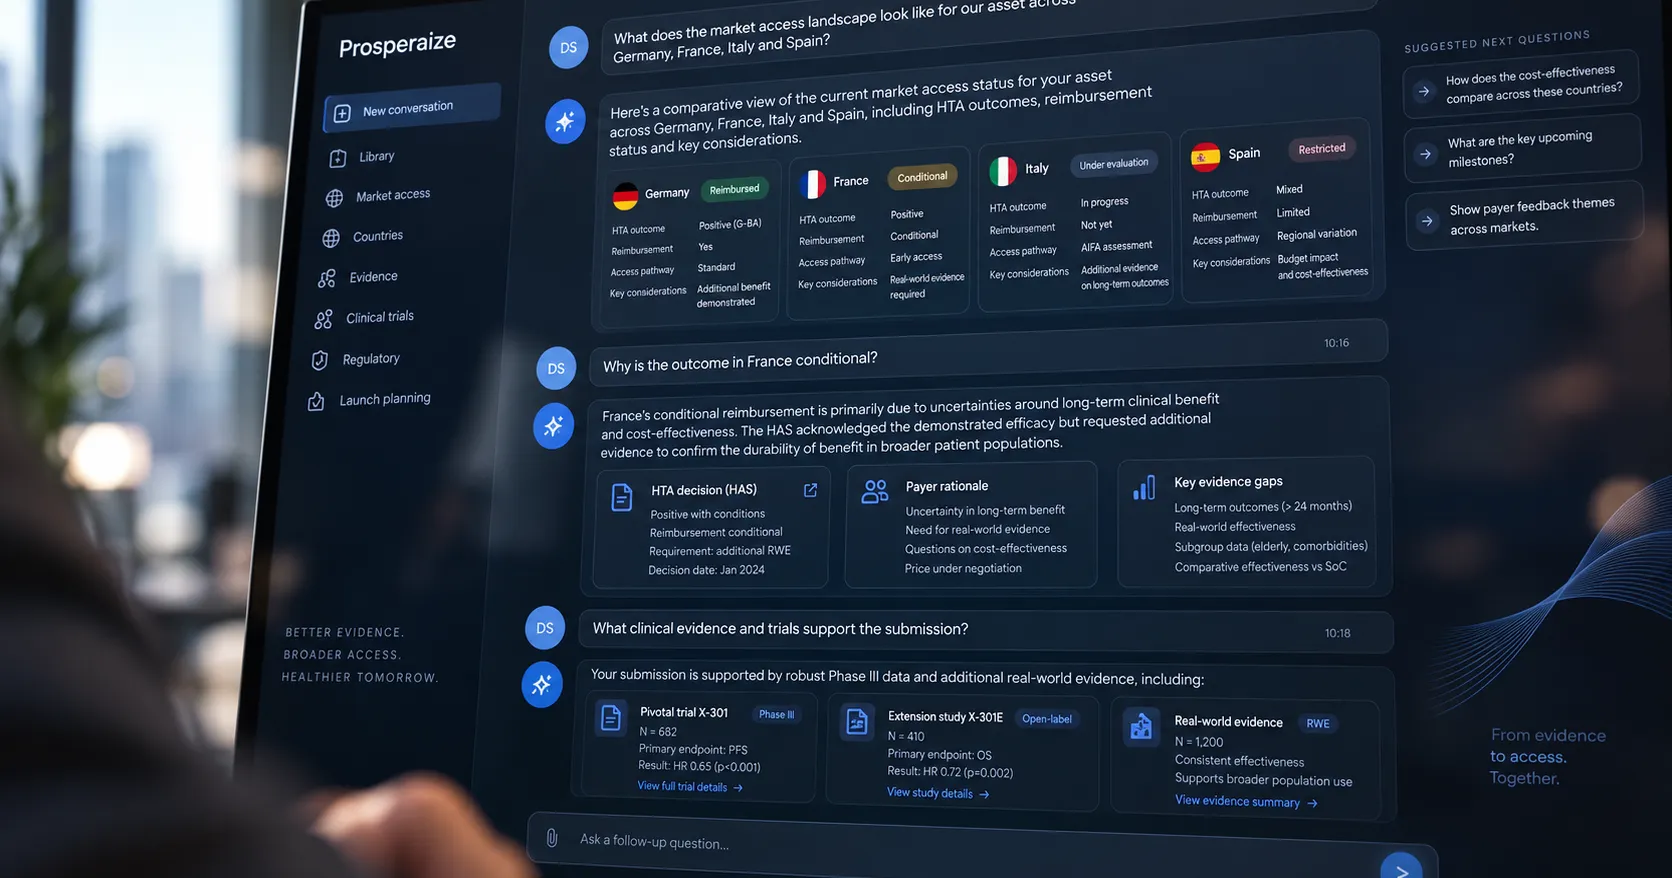

In a first engagement, Prosperaize built a life sciences data company an AI agent that made its pharmaceutical market access data answerable. Users stopped composing filters and started asking questions. Regular use grew to more than half of the platform's users.
That success changed what users asked for. Single questions became chains, each building on the last, and users expected the agent to remember the conversation. At the same time, agentic AI, systems that reason in steps and correct their own course, became viable in production. The company treats its AI layer as a product kept current, not a feature shipped once. Prosperaize proposed a modernization while the system was still succeeding. Engineering leadership approved it.
Prosperaize rebuilt the agent's reasoning on the same knowledge foundation, validated it side by side against the running system, hardened it to production standard, and rolled it out in stages with no interruption to users. The platform's users now hold a working dialogue with the data. Complex, multi-part questions come back in under a minute.
The first engagement ended with the platform answering questions across 300+ columns of regulatory, HTA, and reimbursement data, in every jurisdiction in the dataset, and with regular use at 55% of platform users. The agent did what it was built for: it took a self-contained question and returned a grounded answer.
Then users started asking differently. A landscape question led to a narrowing. The narrowing led to a drill into the evidence behind one decision. That led to the assessment document explaining it. Questions carried more conditions, crossed more of the dataset, and assumed the agent remembered what it had just shown. The first generation answered questions. Users had begun to hold conversations.
Meanwhile the technology moved. Agentic AI, systems that reason in steps, examine intermediate results, and correct themselves, went from research to production viability. The knowledge foundation from the first engagement, the metadata layer and domain-organized views, was exactly what such a system needs to reason against.
The company had a choice most organizations never make deliberately. The system was working. Adoption was growing. Nothing was forcing a change. Prosperaize proposed modernizing anyway, on the grounds that the users had moved, the technology had moved, and the foundation was ready. Engineering leadership made the decision to do it from strength rather than wait until the system fell behind.
Modernizing from strength is cheaper than modernizing from failure, and the only way to never need the latter.
The modernization kept the foundation and renewed the engine. The metadata layer and domain-organized views carried over unchanged. On top of them, Prosperaize built a new reasoning agent. What follows is what the platform's users can now do.
Follow-ups operate on exactly the results the user was just shown. "Of those decisions, which received the higher benefit ratings?" narrows the actual set from the previous answer, not a fresh approximation of it. References like "the most recent one" resolve against what the user saw. Each turn can go deeper, from a landscape to a subset to one decision's trial evidence to the assessment document behind it, without starting over.
In one conversation, a market access user can ask for the HTA landscape for an indication in France and the current first-line options, then narrow to the decisions with the stronger benefit ratings, then ask which clinical trials supported the most recent of those and what kind of studies they were. Three turns. Before, each of those was a separate investigation: filter, export, cross-reference, open documents.
An indication, a set of jurisdictions, a treatment line, a date window, evidence characteristics: combined in a single question and answered as one. This is the long tail beyond any template.
The agent corrects itself. When a first attempt does not hold against the data, it recovers and tries again rather than returning the wrong answer confidently. This is the property that separates an agent that handles the unexpected question from one that handles only the anticipated one.
The agent says what the platform holds and what it doesn't, so users can trust a "no" as much as an answer.
Every answer arrives with the records it came from, linked back to the platform, and with the interpretation choices it made, such as "recent" read as a date window, granted rather than requested ratings. The answer is grounded in the complete result of the question, not a sample of it. For teams whose output feeds regulatory and pricing strategy, an answer they can audit is worth more than an answer alone.
Follow-ups operate on exactly the set the user was just shown. That is what "conversation" means when the answers are precedent.
AI Reliability & Optimization, ongoing
This is the fourth stage of how we work: the stage where we keep improving the live AI system to increase its business value.
The modernization ran the way the original build did: evidence first. Prosperaize developed the new agent against the same knowledge foundation and evaluated it side by side with the running system, same questions, same data, answers and behavior compared directly. It went through an adversarial testing campaign before promotion, then rolled out through the company's environments in stages while the existing system kept serving users. No big-bang cutover. No user disruption. The running system stayed up until its successor had proven itself against it.
This stage does not end. In a live AI asset we look for three signals: where users still leave the system to finish the job, where an answer has to be provable rather than plausible, and where the technology has moved again on a foundation that is already in place. Each one is the next investment, and each costs less than the last because the knowledge layer is already paid for.
The first build made the data answerable. The modernization made it conversational. The same knowledge foundation carried both.
The system delivers results, adoption is steady, and no one is asking what the next generation of the technology would do on your data. Value that is not growing is quietly falling behind.
They ask follow-ups it cannot hold, combine conditions it was not built to combine, or expect it to remember the last answer. The scope was right when it shipped. The users moved.
Agentic systems that reason in steps and correct themselves are now viable in production. If your AI was built before that, the gap between what it does and what is possible on the same data is widening.
If your data is well described and well organized, the intelligence layer can be renewed at a fraction of the original effort. The foundation is the investment. The engine is replaceable.
If you run an AI system that is working and want to know what modernizing it would produce, an AI Reliability & Optimization engagement assesses the system against the current state of the technology and your users' actual questions, and shows what a renewed engine on your existing foundation would do. The working system keeps running while you find out.
Before you fund it, score your project on these ten dimensions. Or accept the downside.
Read more →
Data readiness — not data existence — determines whether an AI initiative ships. Five practices that turn an existing data environment into one AI systems can actually use.
Read more →
AI assets demand a breadth of expertise that no single role, team, or department was ever designed to carry. Here's what actually goes wrong and why.
Read more →API contracts calcify around it. Frontend components lock to its limitations. Services inherit its quirks. The largest sunk cost is the architectural debt shaping every system it touches.
If your AI investment is already exposed, a Prosperity Audit diagnoses whether the problem is architectural, data-related, or both — before the integration tax compounds further.
Get in touch